Human error becomes expensive when a company’s systems allow one missed signal, unclear handoff or rushed decision to spread. High-reliability organizations reduce that risk by treating mistakes as useful data and building safeguards around predictable human limits. Their methods come from fields such as aviation and health care, but growing businesses can apply the same ideas to product launches, customer support, fulfillment and daily operations.
The practical goal is consistent performance under pressure, including the ability to spot weak signals before they become major failures.
Principles of Flawless Execution
Start by making small irregularities visible. The core high-reliability principles include close attention to failure, reluctance to accept simple explanations and respect for frontline expertise. In practice, that means employees need an easy way to report close calls without fearing blame.
Review those reports during a short weekly operations meeting. Ask what happened, which conditions made it possible and where the process needs another safeguard. If three customer orders required manual corrections, for example, inspect the ordering workflow before a larger batch fails. Assign each corrective action an owner and due date. A report without follow-through teaches employees that speaking up changes nothing.
Simulating Disaster Before It Strikes
Run controlled simulations of your most disruptive operating scenarios. Airlines and aviation training organizations use realistic aircraft door trainers to let crews practice normal and emergency procedures in a controlled setting. Businesses can adopt the same principle without needing specialized facilities.
A software company might simulate a six-hour service outage, while a retailer could rehearse losing access to its order platform during a seasonal rush. Give the team incomplete information and introduce a second complication halfway through the exercise. Observe who takes charge, how updates move between departments and where decisions stall. Afterward, record specific gaps in access, staffing and authority. Repeat the exercise after making corrections to confirm that performance has improved.
Standardizing Physical Crew Readiness
Reliable performance also depends on physical readiness. Fatigue, confusing workspaces and poor equipment placement increase the chance that someone will skip a step or misread information. Set clear expectations for shift length, breaks and handoffs, especially for teams handling time-sensitive work.
Standardize the environment so employees can find key tools and instructions without searching. Labels, consistent screen layouts and fixed storage locations reduce unnecessary decisions. Before a demanding shift or launch, supervisors should confirm staffing levels, system access and role assignments. If a team member shows signs of overload, redistribute tasks early. Track overtime, late corrections and repeated handoff issues together because they often reveal the same underlying capacity problem.
Applying Aviation Checklists to Fast Growth
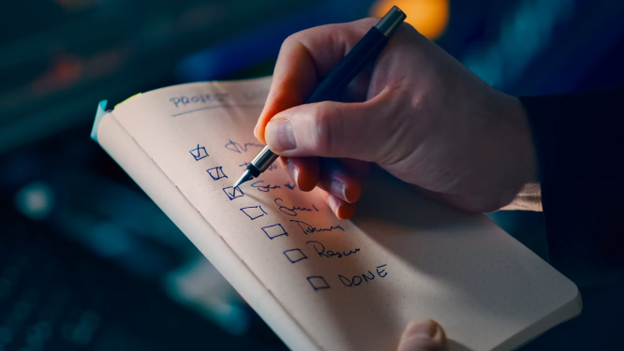
Turn critical workflows into short checklists that support judgment. Each checklist should cover actions that are easy to forget and costly to miss, such as confirming customer approval before production or testing payment processing before a promotion begins. Keep the sequence clear and assign responsibility for every item.
The federal HRO implementation review shows that high reliability requires sustained organizational work, not a one-time training session. Test each checklist with the people who perform the task, then revise confusing language. Review it whenever software, staffing or responsibilities change. For recurring processes, record who completed the checklist and when. That simple audit trail helps managers distinguish a weak process from an isolated oversight.
Reliable organizations expect people to have imperfect attention, especially during unusual or stressful events. They design operations around that reality. The strongest test is simple: when your next disruption occurs, the team should know who decides, where the instructions are and how to keep one problem from spreading.